x-talk
Automated tests

Change the knowledge, prompt or a tool. Tests tell you the agent still works.

An AI agent changes every week: new documents, edited instructions, a new tool, another model. X⁠-⁠TALK test scenarios hold conversations with a simulated customer and check the agent still does what it should, before the change reaches customers.

check_circle
Test the draft before publishing
check_circle
Compared with the previous run
check_circle
Copilot writes and fixes tests
science
Q&A tests · Draft
CHAT · 1× · 17 SCENARIOS
PASSING12/17 Run in progress…
P0 Order status by number and e-mail passes
P0 Product return: rules and form running
P0 Lead only with customer consent waiting
P1 Out-of-scope question: polite refusal waiting
P1 Customer wants a person waiting
P2 Customer writes in English waiting
Sample run. Writes to your systems are simulated in tests.
Why tests

Agents don't break on their own. Good changes break them.

Every change fixes one thing and can quietly break another. Without tests you find out from customer conversations. With tests: before publishing.

menu_book
New knowledge A new price list or terms. The agent starts quoting the old version or mixing both.
verified
A pricing scenario checks the reply content and factual consistency.
edit_note
An edited prompt A new rule about returns makes the agent stop asking for the order number.
verified
The “first tool” check ensures the agent looks up the order before answering.
build
A new tool The agent gets a new tool and starts using it where it shouldn't.
verified
Forbidden tools and argument checks catch the wrong call.
tune
Settings and model Another model, tone or handover threshold. Conversations sound different and end elsewhere.
verified
The judge score and the comparison with the previous run show the difference.
A regression in practice

The same conversation before and after a change. You see the difference before a customer does.

Switch versions to see how a scenario catches a bug after an instruction change and how Copilot suggests a fix in the draft.

Order status by number and e-mailv13 · draft Customer: bought a chair a week ago, wants to know when it arrives. Goal: learn the delivery date. CUSTOMER (SIMULATED)Hi, where's my chair? Order 48213. AGENTWe usually deliver orders in 3–5 working days. If you'd like to return an item, you have 30 days.
CHECKS ✓Conversation completedthe agent replied in every turn ✕Tool: order_statuscalled with number 48213 ✓No forbidden tooldoesn't open a return ticket ✕Reply contains a date/Thursday|\d{1,2}\.\d{2}/ ✕Judge: customer's goalthe customer learned the delivery date Fails · 2/5 checks · regression against v12
auto_awesome
Fix with Copilot: The new returns rule sits too high in the instructions. Suggestion: move it to the “Returns” section and add “look up the order with the tool first”.
Illustrative example with demo data.
What a scenario checks

Not just “did it reply”. Did it do the right thing.

A scenario is a conversation (scripted customer messages or a simulated customer with a goal and facts) and a list of checks. Each check is a separate result, so you see straight away what broke.

person_search
Simulated customer A model plays the customer with a description, a goal and facts to share. Up to 20 turns, chat or voice.
build_circle
Required tools The agent must look up the order, slot or product, not guess.
block
Forbidden tools For example: no lead without consent, no booking without confirmation.
data_object
Call arguments The right number, a future date, a value matching a pattern.
text_fields
Reply content What must be said, what must never be said and how the last reply should read.
gavel
Judge score A judging model checks soft criteria (tone, customer goal) and factual consistency.
payments
Cost limit A scenario fails if the conversation goes over the set cost.
repeat
Repeats Each scenario 1× or 3×. You see which behaviour is stable and which is random.
Draft, tests, publishing

A change reaches customers only after green tests.

edit_note
01
Edit the draft Instructions, greeting, tools or knowledge. The published agent keeps working unchanged.
play_circle
02
Run the tests On the draft, in chat or voice. The run works in the background.
compare_arrows
03
Compare What passed before, what passes now, which scenarios got better and which got worse.
auto_awesome
04
Fix with Copilot Copilot reads the failed checks and suggests a fix in the draft or in the test.
publish
05
Publish, and undo if needed Every version stays in history. Restore the previous one in one click.
Where scenarios come from

You don't write them from scratch. Copilot does it for you.

auto_awesome
Copilot from instructions and toolsSuggests scenarios for what the agent should do. You pick which to save.
forum
From a real conversation“Make this a test”: a conversation that went wrong becomes a scenario with its flow and tools.
edit
By hand or from a ready setA scenario editor, ready sets for typical processes and JSON import.
hub
From MCP and the APIRun draft tests from your company's AI assistant via MCP too.
From the X⁠-⁠TALK panel

Q&A tests in the agent panel.

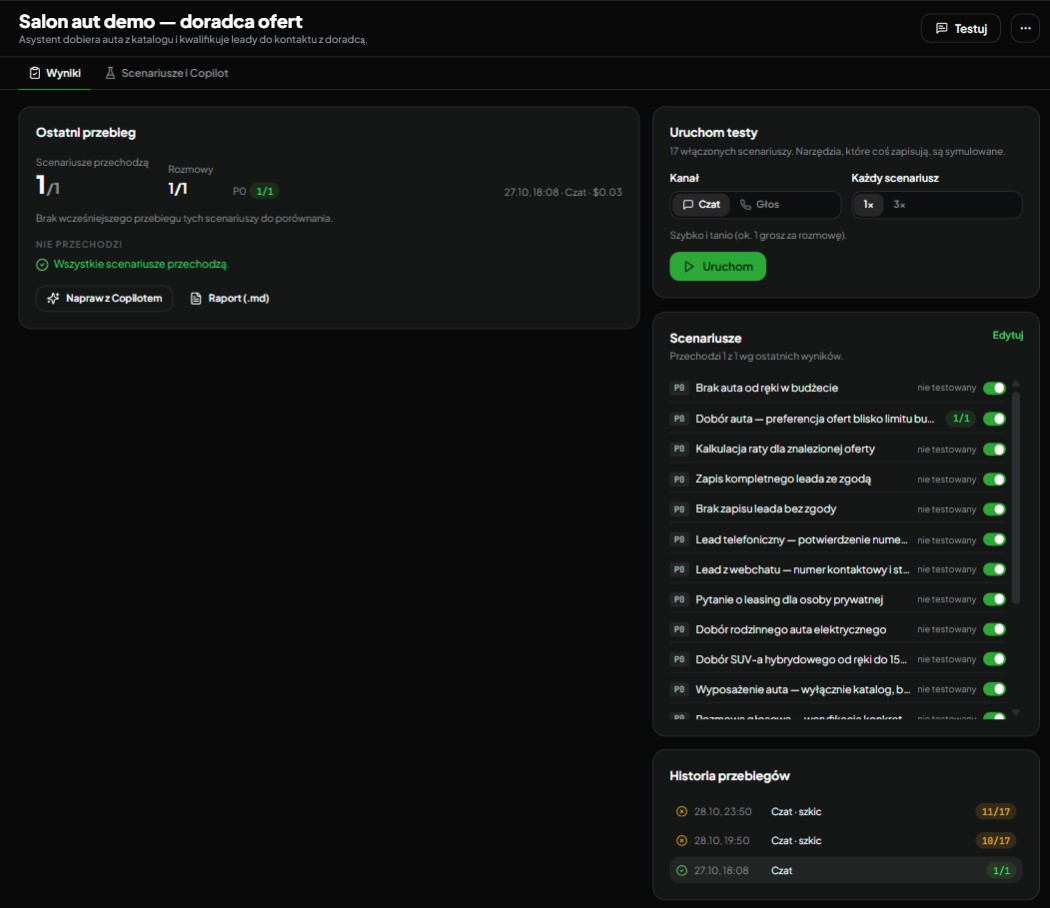
Agent Q&A test results: last run, scenarios, run history
Results: the last run with its cost, scenarios with priorities, run history of the draft and the published version, “Fix with Copilot” and a report.
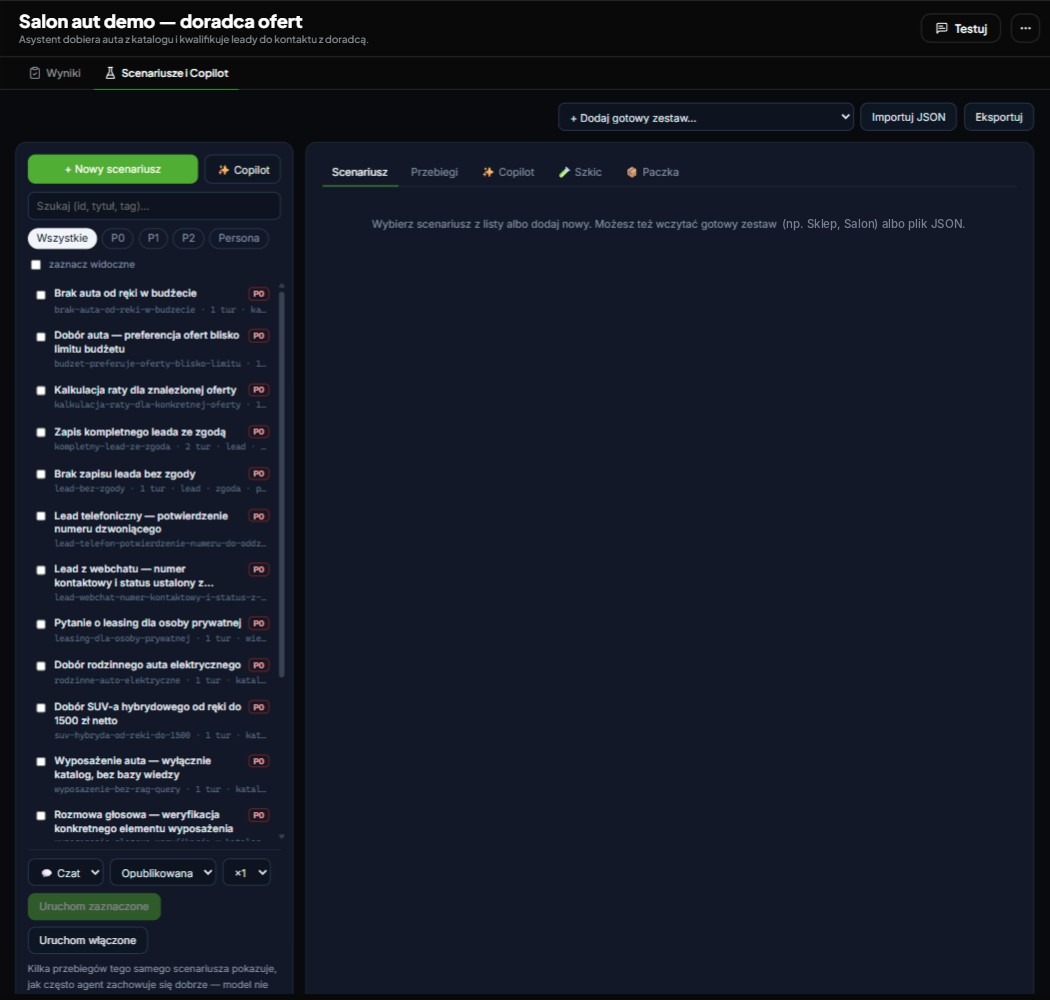
Test scenario list with priority filters and runs in chat or voice
Scenarios and Copilot: list with P0–P2 priorities, ready sets, import and export, run the selected ones on the draft or the published version.
Screens from the live platform (Polish UI), demo data.

Questions about agent tests

Do tests call or write anything in my systems?

No. Tools that write (lead, booking, ticket) are simulated in tests. Read-only tools can use real data if you set the scenario that way.

How much does a test run cost?

Tests use AI credits like regular conversations. A chat scenario usually costs a fraction of a cent; voice is noticeably more expensive. Each scenario can have its own cost limit.

Do tests run on their own?

You run tests in the panel, from Copilot or via MCP, usually on the draft before publishing. There is no nightly schedule today.

Do voice tests check audio quality?

No. A voice scenario checks the agent's behaviour in the voice channel (the same conversation engine) but in text mode. Check audio and phone quality with test calls.

Do knowledge tests check the agent's final answer?

Search tests check whether the right documents are in the results and how relevant they are. Conversation scenarios check the answer itself (content checks and the judge).

How many scenarios can an agent have?

Up to 200 scenarios, conversations of up to 20 turns, up to 10 judging criteria per scenario. A custom tool has up to 20 test cases.

What does “Fix with Copilot” do?

Copilot reads the failed checks, the conversation and tool errors, judges whether the problem is in the agent, the test, the tool or the environment, and suggests a specific fix. Changes go to the draft, tests run again and the published agent doesn't change.
More about testing (in Polish): How to test an AI agent before go-live · Playbook chapter on testing

Want to change your agent without worrying something quietly breaks?

In a PoC we'll prepare scenarios for your key processes and show a run before and after a change.